Advancing AI Reliability through Research & Engineering
Applying 26 years of reliability discipline to the hardest problems in enterprise AI.
Ecosystem
We build on the platforms enterprises already trust.
We work across every major AI model, cloud environment and agent platform, and connect into the systems your teams already use.

Models
Models & foundation
 Anthropic
 OpenAI
 Gemini
 Amazon Bedrock
 Nvidia
 ElevenLabs
 Kore.ai
 Cognition (Devin)
 Cursor
 DevRev
Integrations
100+
Connectors


Environments
Cloud & deploy
- AWS
- Google Cloud
 Azure
 Oracle
- Kubernetes
 Private VPC
 On-premise
Connectors

Connectors
Observability & on-call
- Datadog
- Dynatrace
- New Relic
 Splunk
- Grafana
 Prometheus
 AppDynamics
 Elastic
- PagerDuty
 Opsgenie

Connectors
ITSM
 ServiceNow
- Jira
 Freshservice

Connectors
Data & channels
- Salesforce
- Postgres
- Kafka
- Slack
Trust in production
The hard part of enterprise AI isn’t starting,
it is earning trust in production.
57%
of organizations now run AI agents in production.
32%
say quality is the #1 barrier to deploying more.
Source: LangChain State of Agent Engineering, 2025
Anyone can prototype an AI system. Very few can put one in front of a regulated enterprise’s customers and stand behind every decision it makes. QK AI Labs exists to solve one problem: trust in production. It follows the path any real system travels: you Build it, you Prove it works, and you keep it Running once it’s live.
Build
Applied AI & Agent Engineering
We build AI systems and agents as evaluated, governed, reusable IP, not one-off scripts, and our engineers embed with enterprise teams to build them on any stack.
20+
AI-led projects
100+
Applied AI engineers
Prove
AI Evaluation & Assurance
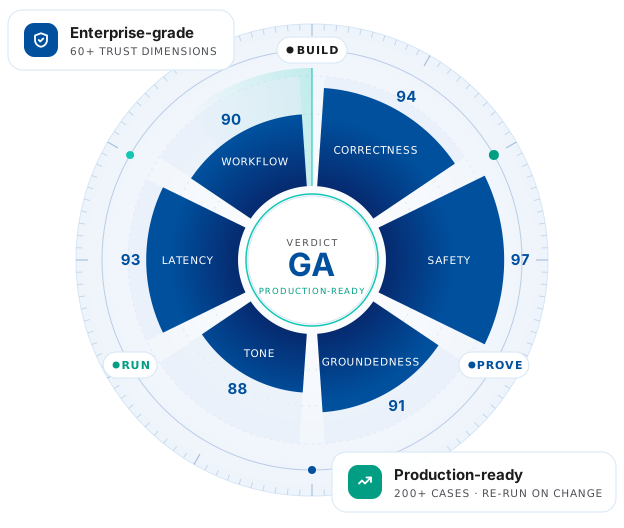
An AI system has no native unit test, so we built the measurement system. We generate hundreds of realistic test cases from a plain-English description, score every response across a multi-dimension framework (correctness, safety, groundedness, tone, latency, workflow reliability), and turn each release into a pass/fail deployment verdict. Governance with identity, data controls, human-in-the-loop, audit, is applied at every step, not just as a final gate.
60+
scoring dimensions
200+
Test cases auto-generated per system
Run
AI Reliability & Operations (AI Ops)
We turn millions of production signals into real-time answers, correlating events, finding root cause, and driving incidents toward resolution before customers feel them, connected into the observability, on-call and ITSM stack the enterprise already runs.
~90%
Alert-noise reduction
30–58%
MTTR improvement
<15 min
Root cause
80%+
CSAT in production
100+
Enterprise connectors
How we measure
Vibe-checking doesn’t scale.
Systematic evaluation does.
AI systems fail differently from normal software. The same input can produce different outputs, the failure surface is unbounded, and behavior drifts silently when the model updates.
So we treat evaluation as a measurement problem, not a review. Describe a system in plain English, detect the domain, generate hundreds of realistic test cases (core, edge, adversarial, and probe), run them against the live system, score every response across the framework, and produce an Alpha to GA verdict with per-dimension guidance on what to fix. Then we re-run continuously to catch drift.
Describe
a system in plain English
Detect
the domain
Generate
core · edge · adversarial · probe
Run
against the live system
Score
every response
Verdict
Alpha → GA, per-dimension guidance
Re-run continuously to catch drift
We score for
Correctness
Safety
Production behaviour
Platform · Custom · Pre-built
From lab prototype to production system.
QK AI Labs develops the methods, frameworks and engineering practices that power QKTech’s AI offerings. As enterprise AI shifts from pilots to production systems, QK AI Labs offers these capabilities to enterprises through three paths: Techniqk, Agentiqk and Marqk. And this is how our decades of research become your most reliable running system.
Platform
the platforms
26 years of expertise in quality engineering, reliability, performance and enterprise operations is infused into QKTech’s home-grown platforms. These AI-powered platforms help businesses build, run, secure, scale and assure reliable digital experiences end to end.
Custom
custom agents
Agentiqk is QKTech’s custom agent engineering platform that helps enterprises design, build, evaluate, and deploy AI agents tailored to their workflows, data, and governance requirements. It enables organizations to move from AI use cases to production-ready agents through a structured, enterprise-grade delivery lifecycle.
Pre-built
pre-built agents
Marqk is a marketplace of industry-specific and function-specific pre-built AI agents that enable organizations to accelerate AI adoption through ready-to-use solutions that can be evaluated, customized, and deployed with minimal effort.
The research behind reliable AI
Whitepaper
The Bridge Pattern for AI Observability
AI agents in vendor runtimes can’t be instrumented, so how do you see what they’re really doing? Learn how a proxy rebuilds their traces and exposes failures confident replies hide.
Read more
Whitepaper
Evaluating AI Agents in Production
Six of seven production AI agents failed critical checks despite strong quality scores. Read it to see why averages mislead and how to set pass/fail criteria that show an agent is ship-ready.
Read more
Measured outcomes
The evidence, in production.
Every result here comes from real enterprise work.
~90%
alert-noise reduction in enterprise operational intelligence deployments.
60+
scored dimensions that improve customer experience, build trust, and maximize ROI.
80%+
customer satisfaction measured through AI-led customer experience monitoring.
24/7
single-pane visibility achieved through unified monitoring of multiple data sources.
40–50%
more defect detection achieved through AI-led digital assurance and reliability practices.
30–58%
MTTR improvement observed across production AIOps implementations.
Forward-Deployed Engineering
The lab, and the expertise behind it.
A Forward-Deployed Engineering core of architects, consultants and agent engineers, backed by solutioning, delivery and governance, and 26 years of QKTech reliability expertise.
26 years
Engineering digital reliability
40+
Certified practitioners
300+
Clients
25+
Countries
12K
Applications assured
Certified on
- AWS
- GCP
- Azure
- Oracle
- DevRev
Talk to the AI Lab Expert
Book a consultation with our AI Expert and bring us a use case. We will help you with a measurable path to production.